15 posts tagged with "semantic-router"

View All Tags

Adding Cursor-Style Auto Model Selection to OpenCode with vLLM Semantic Router

· 11 min read
Anup Sharma
AI & Distributed System @ Nutanix
Aayush Saini
SDE, Data and AI @ Red Hat
Shivji Kumar Jha
Staff Engineer (Data & AI) @ Nutanix

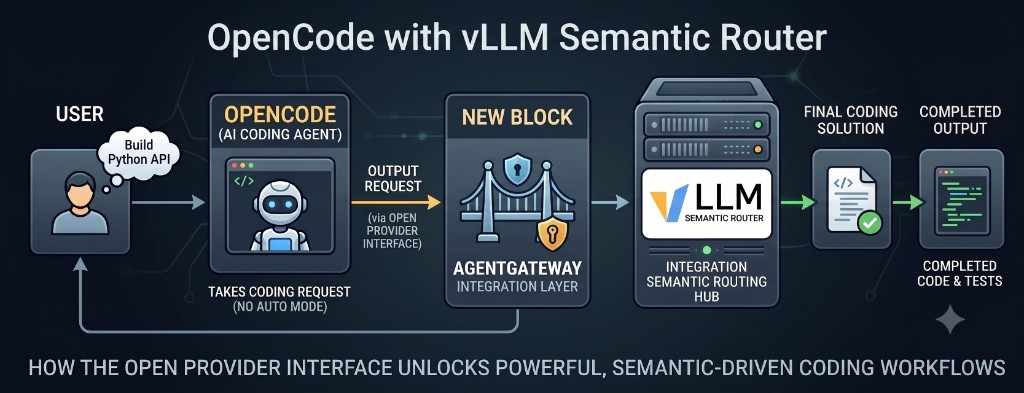
OpenCode with vLLM Semantic Router: open provider interface, AgentGateway integration layer, and semantic routing hub

The Feature Everyone Wants and Almost Nobody Has​

Cursor's Auto mode is deceptively simple: the developer types, and the IDE chooses whether a prompt deserves a frontier model or something faster and cheaper. It is easy to stop noticing — until moving to an open tool where every request starts with a model dropdown.

Giving AgentGateway a Semantic Brain with vLLM Semantic Router

· 10 min read
Aayush Saini
SDE, Data and AI @ Red Hat
Anup Sharma
AI & Distributed System @ Nutanix

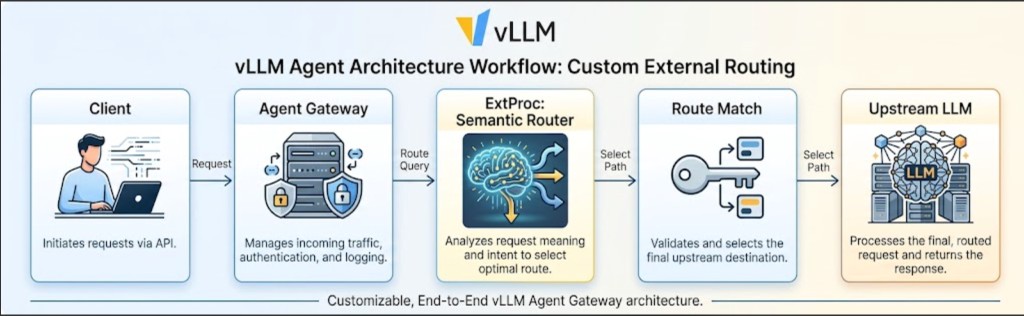
vLLM Agent Architecture Workflow: Custom Semantic Routing with AgentGateway and Semantic Router

Agent systems that span multiple models — a local endpoint for coding, a frontier cloud model for deep reasoning, and a fast general-purpose model for everyday tasks — all face the same routing question: how should each request be directed to the right backend?

Many deployments start with a lightweight Python proxy or keyword matcher in front of the gateway. That approach works at small scale, but misroutes grow quickly as traffic, languages, and task types diversify. This post shows how vLLM Semantic Router running as an Envoy ExtProc sidecar inside AgentGateway replaces that pattern with semantic, config-driven routing.

Agentic Routing on AMD ROCm

· 14 min read
Xunzhuo Liu
Intelligent Routing @vLLM | Open Source & AI @AMD
Haichen Zhang
Sr. AI Engineer @AMD
Andy Luo
Sr. Director @AMD

Most agent systems start with a simple idea: call model: auto and let the inference layer pick the right model. That is useful, but it is not enough for long-running agents.

A coding agent can begin with architecture work, call tools, receive short tool outputs, continue with "fix that", then ask a privacy-sensitive question in the same user session. The latest message may look simple, but the route cannot be chosen from the latest message alone. The router also has to know whether this is a safe moment to switch models.

This guide shows how to deploy that pattern on AMD ROCm with vLLM Semantic Router. You will start one ROCm vLLM backend, serve the agentic routing recipe, open the dashboard, validate the OpenAI-compatible API, and use Inferoa to experience route decisions and Router Learning behavior from an agent client.
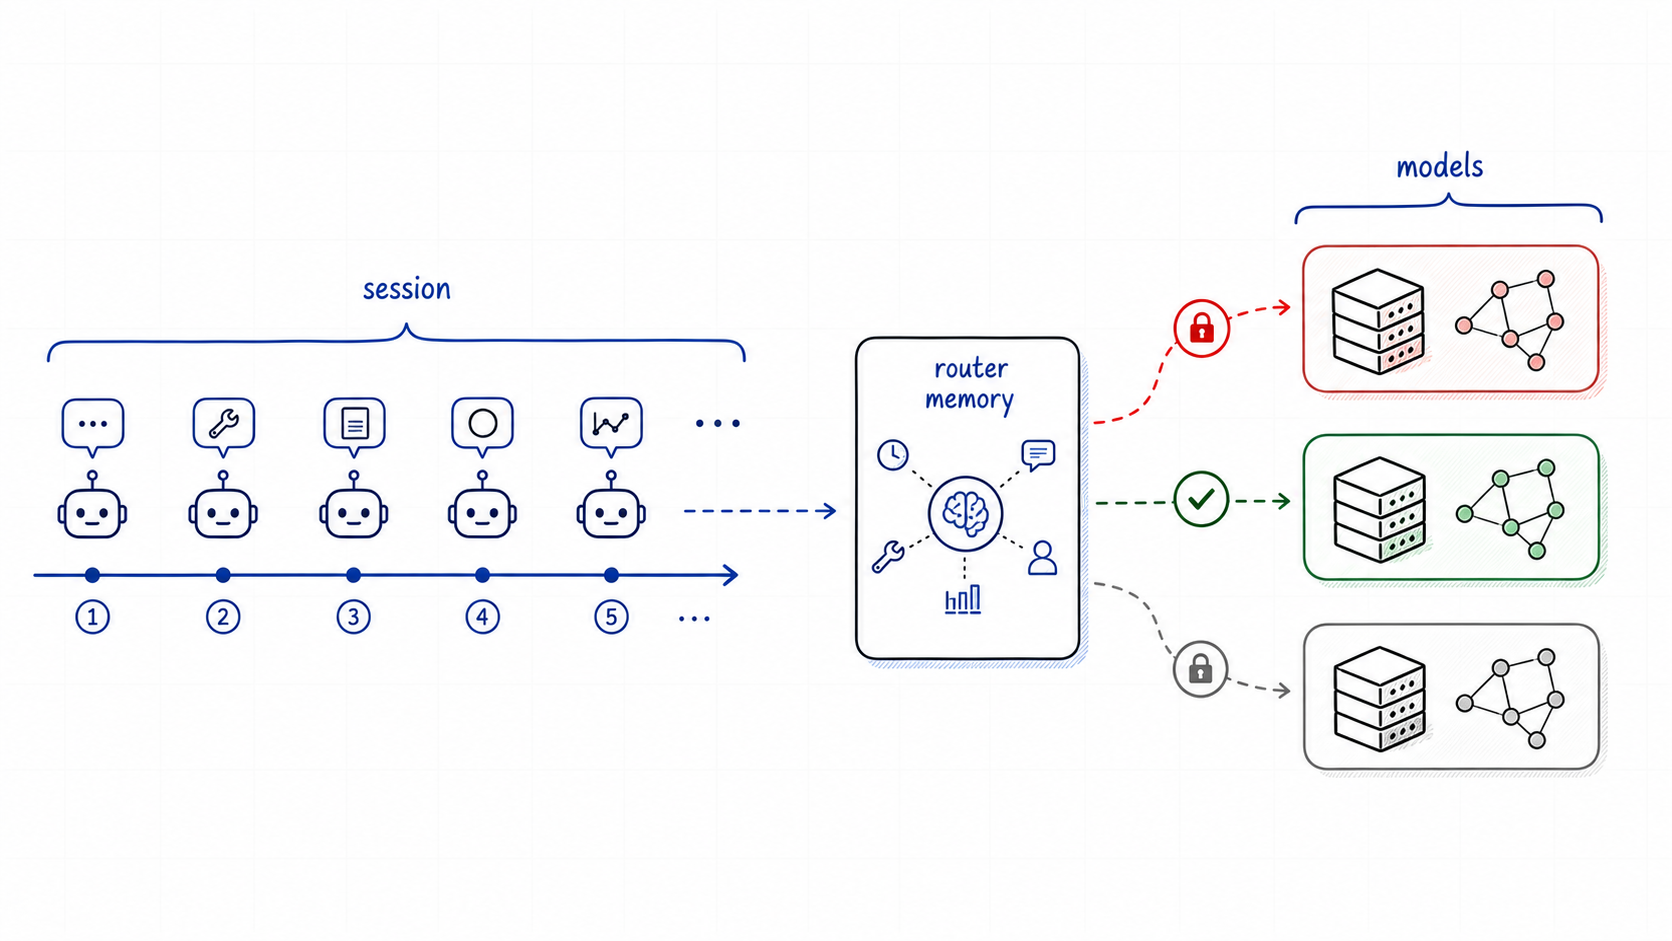
Agent session routed through router memory to model paths
Agentic routing is not only choosing a model. It is choosing when to keep one.
Deploying vLLM Semantic Router on AMD Developer Cloud

· 12 min read
Xunzhuo Liu
Intelligent Routing @vLLM | Open Source & AI @AMD
Haichen Zhang
Sr. AI Engineer @AMD
Andy Luo
Sr. Director @AMD

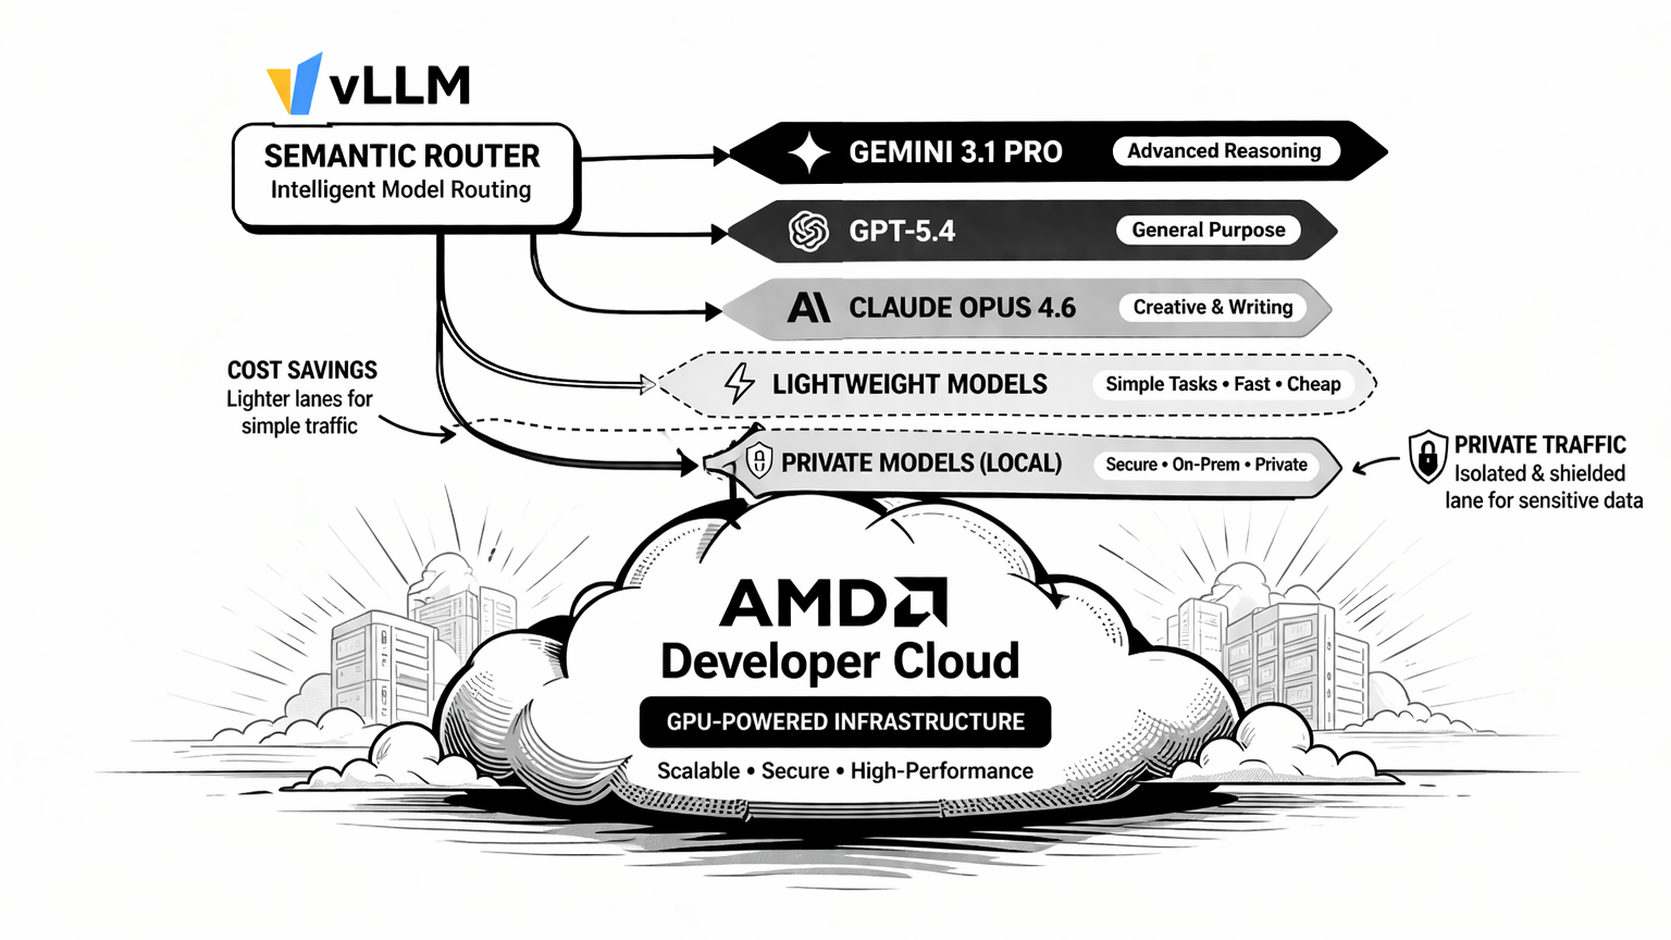
AMD Developer Cloud and vLLM Semantic Router overview

Running vLLM Semantic Router on AMD Developer Cloud is not just about bringing up one more inference endpoint. It is about turning it into a routed multi-tier system that can classify requests, choose a semantic lane, and make replay and Insights immediately useful.

This post walks through the practical path: start the ROCm backend on an AMD Developer Cloud instance, install vLLM-SR, import the reference profile, and validate the deployment end to end.

v0.3 Themis Roadmap: Stability at Scale

· 10 min read
Xunzhuo Liu
Intelligent Routing @vLLM | Open Source & AI @AMD
Huamin Chen
AI @Microsoft

v0.3, codename Themis, is our production-readiness release for Semantic Router. The theme is simple: Stability at Scale. After Athena expanded the system brain, Themis is the release where we make that intelligence dependable across real environments, clearer to operate, and safer to ship into production.

This roadmap is not just about adding more capability. It is about making the full system coherent: one stable contract across Docker and Kubernetes, one cleaner deployment path, one real version story for images and packages, stronger performance validation on both NVIDIA and AMD, and a research track that directly improves the product instead of sitting outside it.

img