Vela 2.0: Open Foundation Routing Models

Still one model. Still one request. Now with spans. Sound on.
Open Foundation Routing Models. Bringing span-level decisions to System One.
Vela 2.0 is a family of open models for routing, safety checks and span-level decisions. Define your options, labels and rubrics at request time; get structured answers with probabilities and character-offset spans through one SystemOne-compatible interface.
Explore the four models → · Read about Decision →
- One model for routing and guardrails. Combine domain, safety, PII and hallucination questions in one request.
- Decisions that locate text. Find personal data, unsupported claims and extractive evidence as labelled spans with character offsets.
- Tasks defined by your application. Supply choices, yes/no criteria, ordered rubrics and label sets when you call the model.
Choose your model
| Model | Positioning | Parameters | Input | Span heads |
|---|---|---|---|---|
| Vela-2.0-0.3B | Compact encoder for CPU and ONNX deployments | 307M | 8,192 tokens | router |
| Vela-2.0-0.8B | Smallest hybrid model with open-label extraction | 756M | 16,384 tokens | router + broad |
| Vela-2.0-4B | Balanced hybrid model for routing and safety | 4.2B | 16,384 tokens | router + broad |
| Vela-2.0-9B | Flagship: strongest measured general decisions and long-document PII in the family | 7.9B | 16,384 tokens | router + broad |
Quickstart
Start with the 0.3B encoder on CPU:
pip install torch "transformers>=5.17" safetensors tokenizers numpy
from transformers import AutoModel

m = AutoModel.from_pretrained("vllm-sr/Vela-2.0-0.3B", trust_remote_code=True)
result = m.system_one(
    state={"request": "Email Tom Baker at tom.baker@example.com."},
    questions={
        "route": {"type": "choice", "instructions": "What does this request ask for?",
                  "criteria": {"email": "send an email", "other": "another task"},
                  "over": "request"},
        "pii": {"type": "span", "instructions": "Which spans are personal information?",
                "criteria": m.vela2_engine.cal["pii_schema"]["labels"], "over": "request"}})
print(result["answers"])
print(result["spans"])
The same question format works at every size. The GPU example below combines request routing with PII and grounded hallucination checks.
Why decision models
Vela 1.0 gave each routing signal its own model and fixed label set. Decision models let the application define the question and its answers at request time: a Choice among options, a Noul (yes/no) probability or a Score over ordered levels.
Vela 2.0 brings Span and Set answers to that interface, alongside training on the router's safety, prompt-attack, PII and hallucination signals. One request can ask which route to take, whether it is safe and which words require action.
The hybrid models build on Decision 2.0's Eos-0.8B, Nox-4B and Lux-9B, using Qwen3.5 text backbones to score supplied answers without generating text. The compact encoder starts from Decision-1.0-Kai's Choice trunk.
One request, every question
Every Vela 2.0 model takes the same request: a state (plain text, or named parts such as request, context and answer) and named questions of five types. Choice, Noul and Score keep the decision format unchanged. Span questions return {label, start, end, text, probability} with offsets into the part they are asked over; set questions select labels with a probability for each.
In the decoders, the state prefix is read once per rendered sequence. Every question continues from that prefix in its own causal block. Full-attention layers reuse the prefix's keys and values; Gated-DeltaNet layers reuse its recurrent state and convolution tail. Each block sees the prefix and itself, with no connection to another question's block.
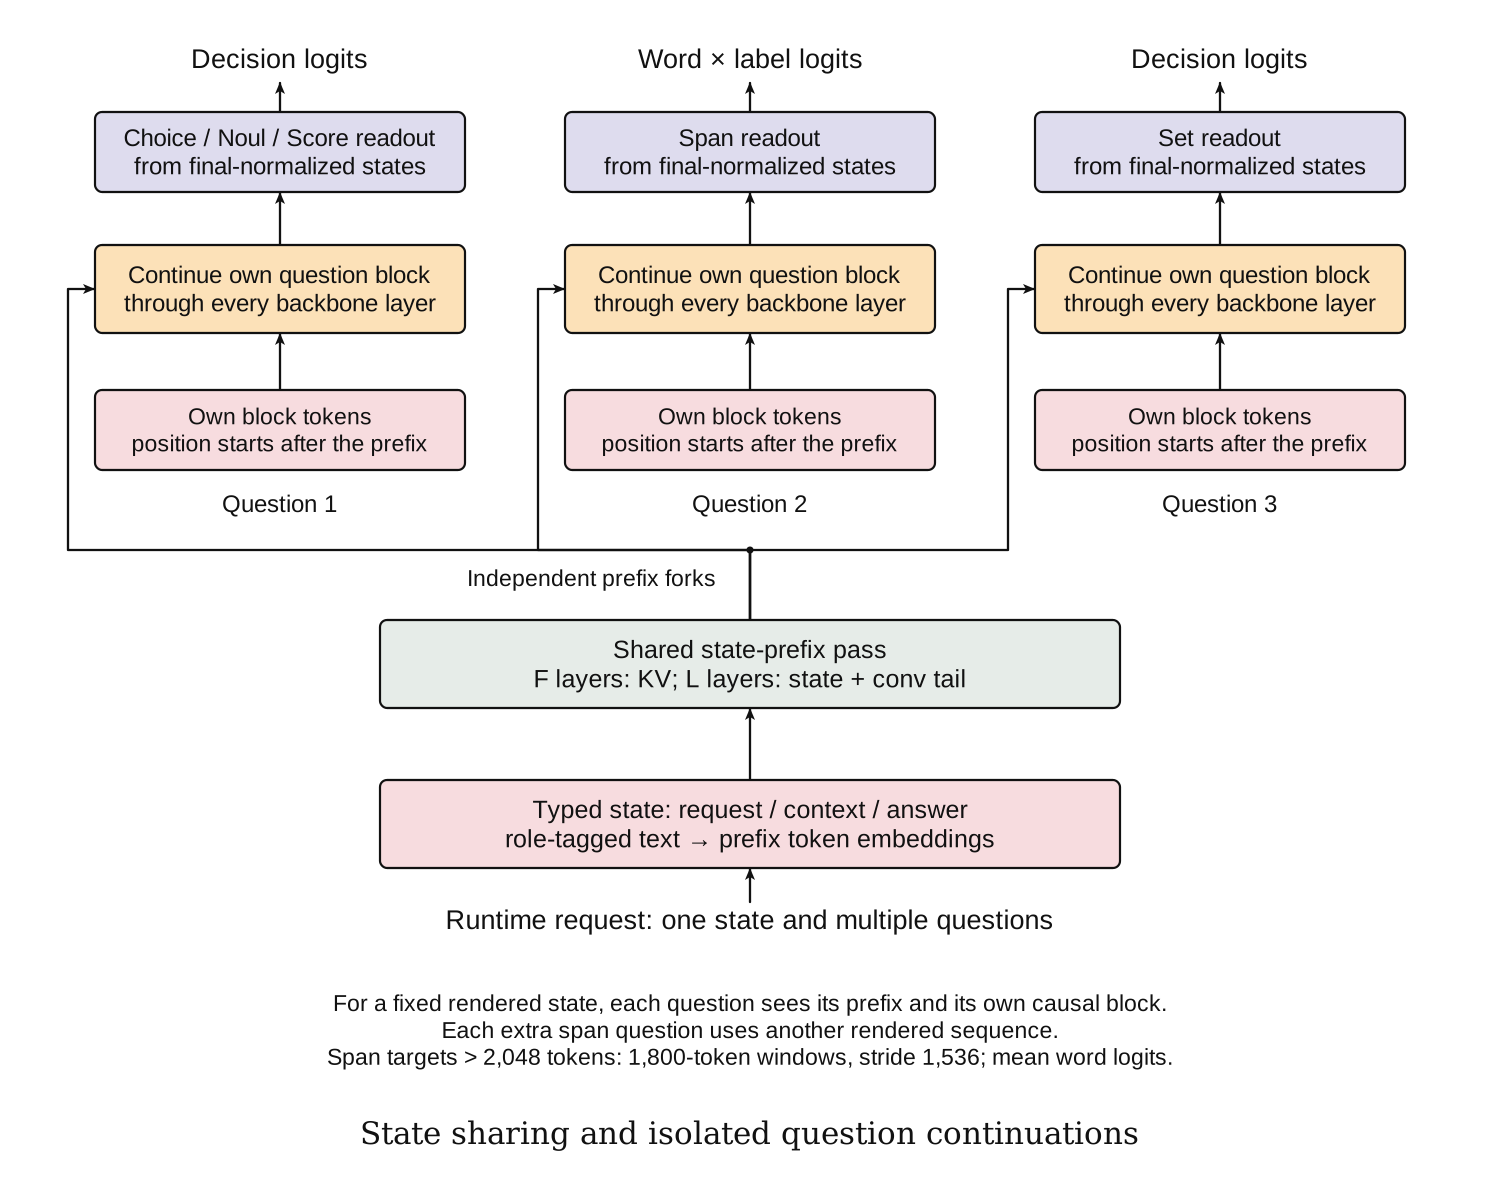
For a fixed rendered state, each decoder question sees only the prefix and its own causal block. The prefix forks independently at every layer.
The 0.3B encoder uses the same interface, reading the questions and state together in a bidirectional sequence.
Decoder execution and long inputs
Questions are isolated for a fixed rendered state. Extra span questions use separate rendered sequences, and span targets longer than 2,048 tokens use additional window sequences. Adding questions can change how text is truncated to fit the input budget. These sequences stay behind one API call.
Spans inside a decision model
A span question is a grid of yes/no decisions: one for every word of the text and every label in the question. Is Tom part of a PERSON? Is tom.baker@example.com an EMAIL_ADDRESS? Words that say yes for the same label and sit next to each other become one span, with character offsets into the original text. The question's entry in answers also exposes the grid's highest word probability as a Noul.
A span question looks like any other question, with a label block in place of options:
"pii": {"type": "span",
        "instructions": "Which spans are personal information?",
        "criteria": {"PERSON": "a person's name", "EMAIL_ADDRESS": "an email address"},
        "over": "request"}
Inside a decoder, the span block is laid out as its instructions, then one label block per label (name and description), then a second copy of the target text. For one short-target span question, the tree forward produces every vector the selected span head needs:
- A vector per label. LayerNorm of the mean hidden state over the label's whole block, plus a learned slot embedding. With two or more labels, these vectors are centred by subtracting their mean.
- A vector per word. The hidden state of the word's first sub-word token, read from the second copy of the text, then LayerNorm and centring over the target's words.
- A score per word × label. A bilinear + MLP scorer rates every pair in FP32.
- Spans. The grid logits are temperature-scaled and passed through a sigmoid. Pairs above the chosen threshold are switched on, neighbouring words with the same label are merged, and word offsets become character offsets.
Conceptually, for one span question:
parts_h, blocks_h = tree_backbone(state_prefix, question_blocks)
head   = choose_span_head(question)                  # router or broad weights
labels = head.label_norm(mean_pool(blocks_h, label_blocks))  # [L, H]
labels = labels + head.slot_embedding[arange(L).clamp(max=63)]
labels = labels - labels.mean(0) if L >= 2 else labels
words  = head.word_norm(blocks_h[first_subword_positions_in_copy])  # [W, H]
words  = words - words.mean(0)
logits = head.bilinear_plus_mlp(words, labels)         # [W, L], FP32
probs  = sigmoid(logits / head_temperature)
spans  = decode_spans(probs, threshold)                # highest-label words, merge, trim
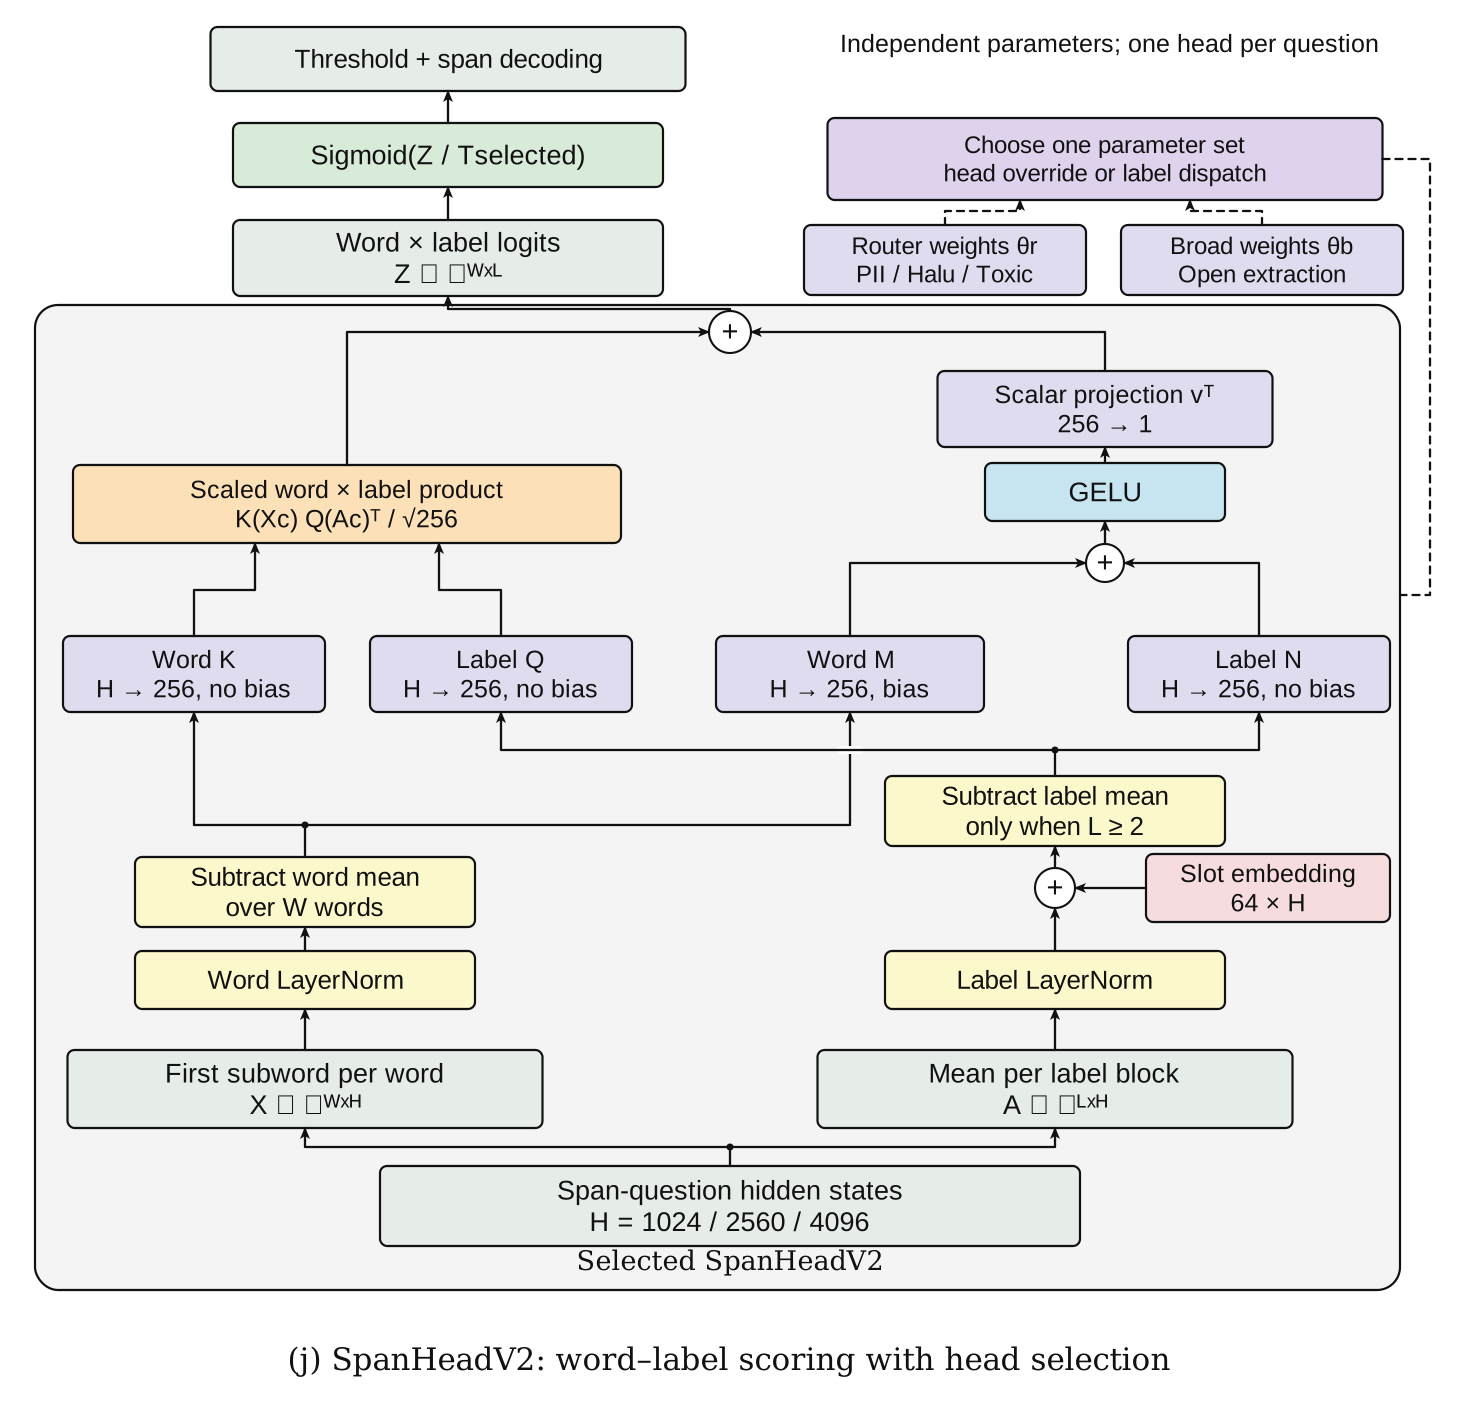
Router and broad heads share this topology, with independent parameters. Dispatch selects the head and its calibration; the resulting word × label grid is decoded into spans.
Two choices make this work in a causal decoder:
- Read words from a second copy. Under a causal mask, a word's state sees only the words to its left, which is the wrong view for deciding where an entity starts and ends. In the second copy, placed after the labels, every word has already seen the whole text and every label it is asked about. Targets up to 2,048 tokens are copied whole; longer ones are read in overlapping windows of up to 1,800 tokens with stride 1,536. Word logits are averaged across covering windows before temperature scaling and sigmoid.
- Read each label from its whole block. Our first decoder span head read each label at a single marker token. The label vectors came out almost identical (pairwise cosine 0.997), so the head learned whether a word is an entity but not which one. Pooling over the name and description separates the labels, and it lets a question use labels the model has never seen: the label is understood from its description.
On development data, the two changes together raise short-text PII F1 from 0.828 to 0.959, and PII F1 on long documents from about 0.06 to 0.94.
The 0.3B encoder needs neither change. It reads the questions and the text in one bidirectional sequence, so every word already sees both sides and every label, and its span head scores word × label pairs by cosine similarity.
Two span heads, chosen per question
The decoders carry two span heads of the same form with separate weights:
- the router head, trained on PII, unsupported claims and toxic spans, the signals a router acts on;
- the broad head, trained on open extraction: named entities of any type, relations, entity mentions and extractive evidence for a question.
The broad head trains last, with the backbone, the decision heads and the router head frozen. Every router output is therefore bitwise identical with and without it; we checked this on 700 rows per model. By default, dispatch recognises the pii, halu and toxic question IDs, the router's label sets, PII subsets and hallucination aliases. Other labels go to the broad head, and the response names the head that answered. An explicit head field overrides the rule.
The result is one model that is a router signal model and an open extractor at once, with no change to its routing behaviour. The 0.3B encoder ships with the router head.
Where Vela 2.0 sits
Vela 2.0 sits between two lines of work: span extractors that read labels at request time, and decision models that answer typed questions.
| Typed decisions (Choice / Noul / Score) | Spans for labels named in the request | Grounded check (context vs answer) | Trained on router safety, PII and hallucination | |
|---|---|---|---|---|
| GLiNER | — | entities | — | — |
| GLiNER2 | classification | entities and structured fields | — | — |
| LettuceDetect | — | fixed label (unsupported) | yes | hallucination only |
| Decision 2.0 | yes | — | — | — |
| Vela 2.0 | yes | router spans; hybrids add a broad head | yes | yes |
GLiNER showed that a span extractor can read its labels from the request, and GLiNER2 extended that to classification and structured extraction in one schema. Vela 2.0 combines the SystemOne decision format with routing-specific training and grounded checks, following GLiNER2's label resampling recipe.
Results
The router comparisons use identical test rows and paired bootstraps; open extraction uses a shared harness. The charts retain the reported evaluation protocols, described below and in each model card.
Selection protocol. Checkpoint selection used development splits. The 0.3B card records that final release selection also considered test results and its shipped PII threshold floor was lowered after the test effect was observed.
- Prompt attacks
- 0.989AUC · unseen attack families · 9Bfrom 0.792 · Vela 1.0 Guard
- Multilingual hate speech
- 0.855AUC · Multilingual HateCheck · 9Bfrom 0.646 · Vela 1.0 Safety
- Extractive evidence
- 24.5word-F1 · ACL-Verbatim, held out · 9Bfrom 7.0 · best GLiNER-family model
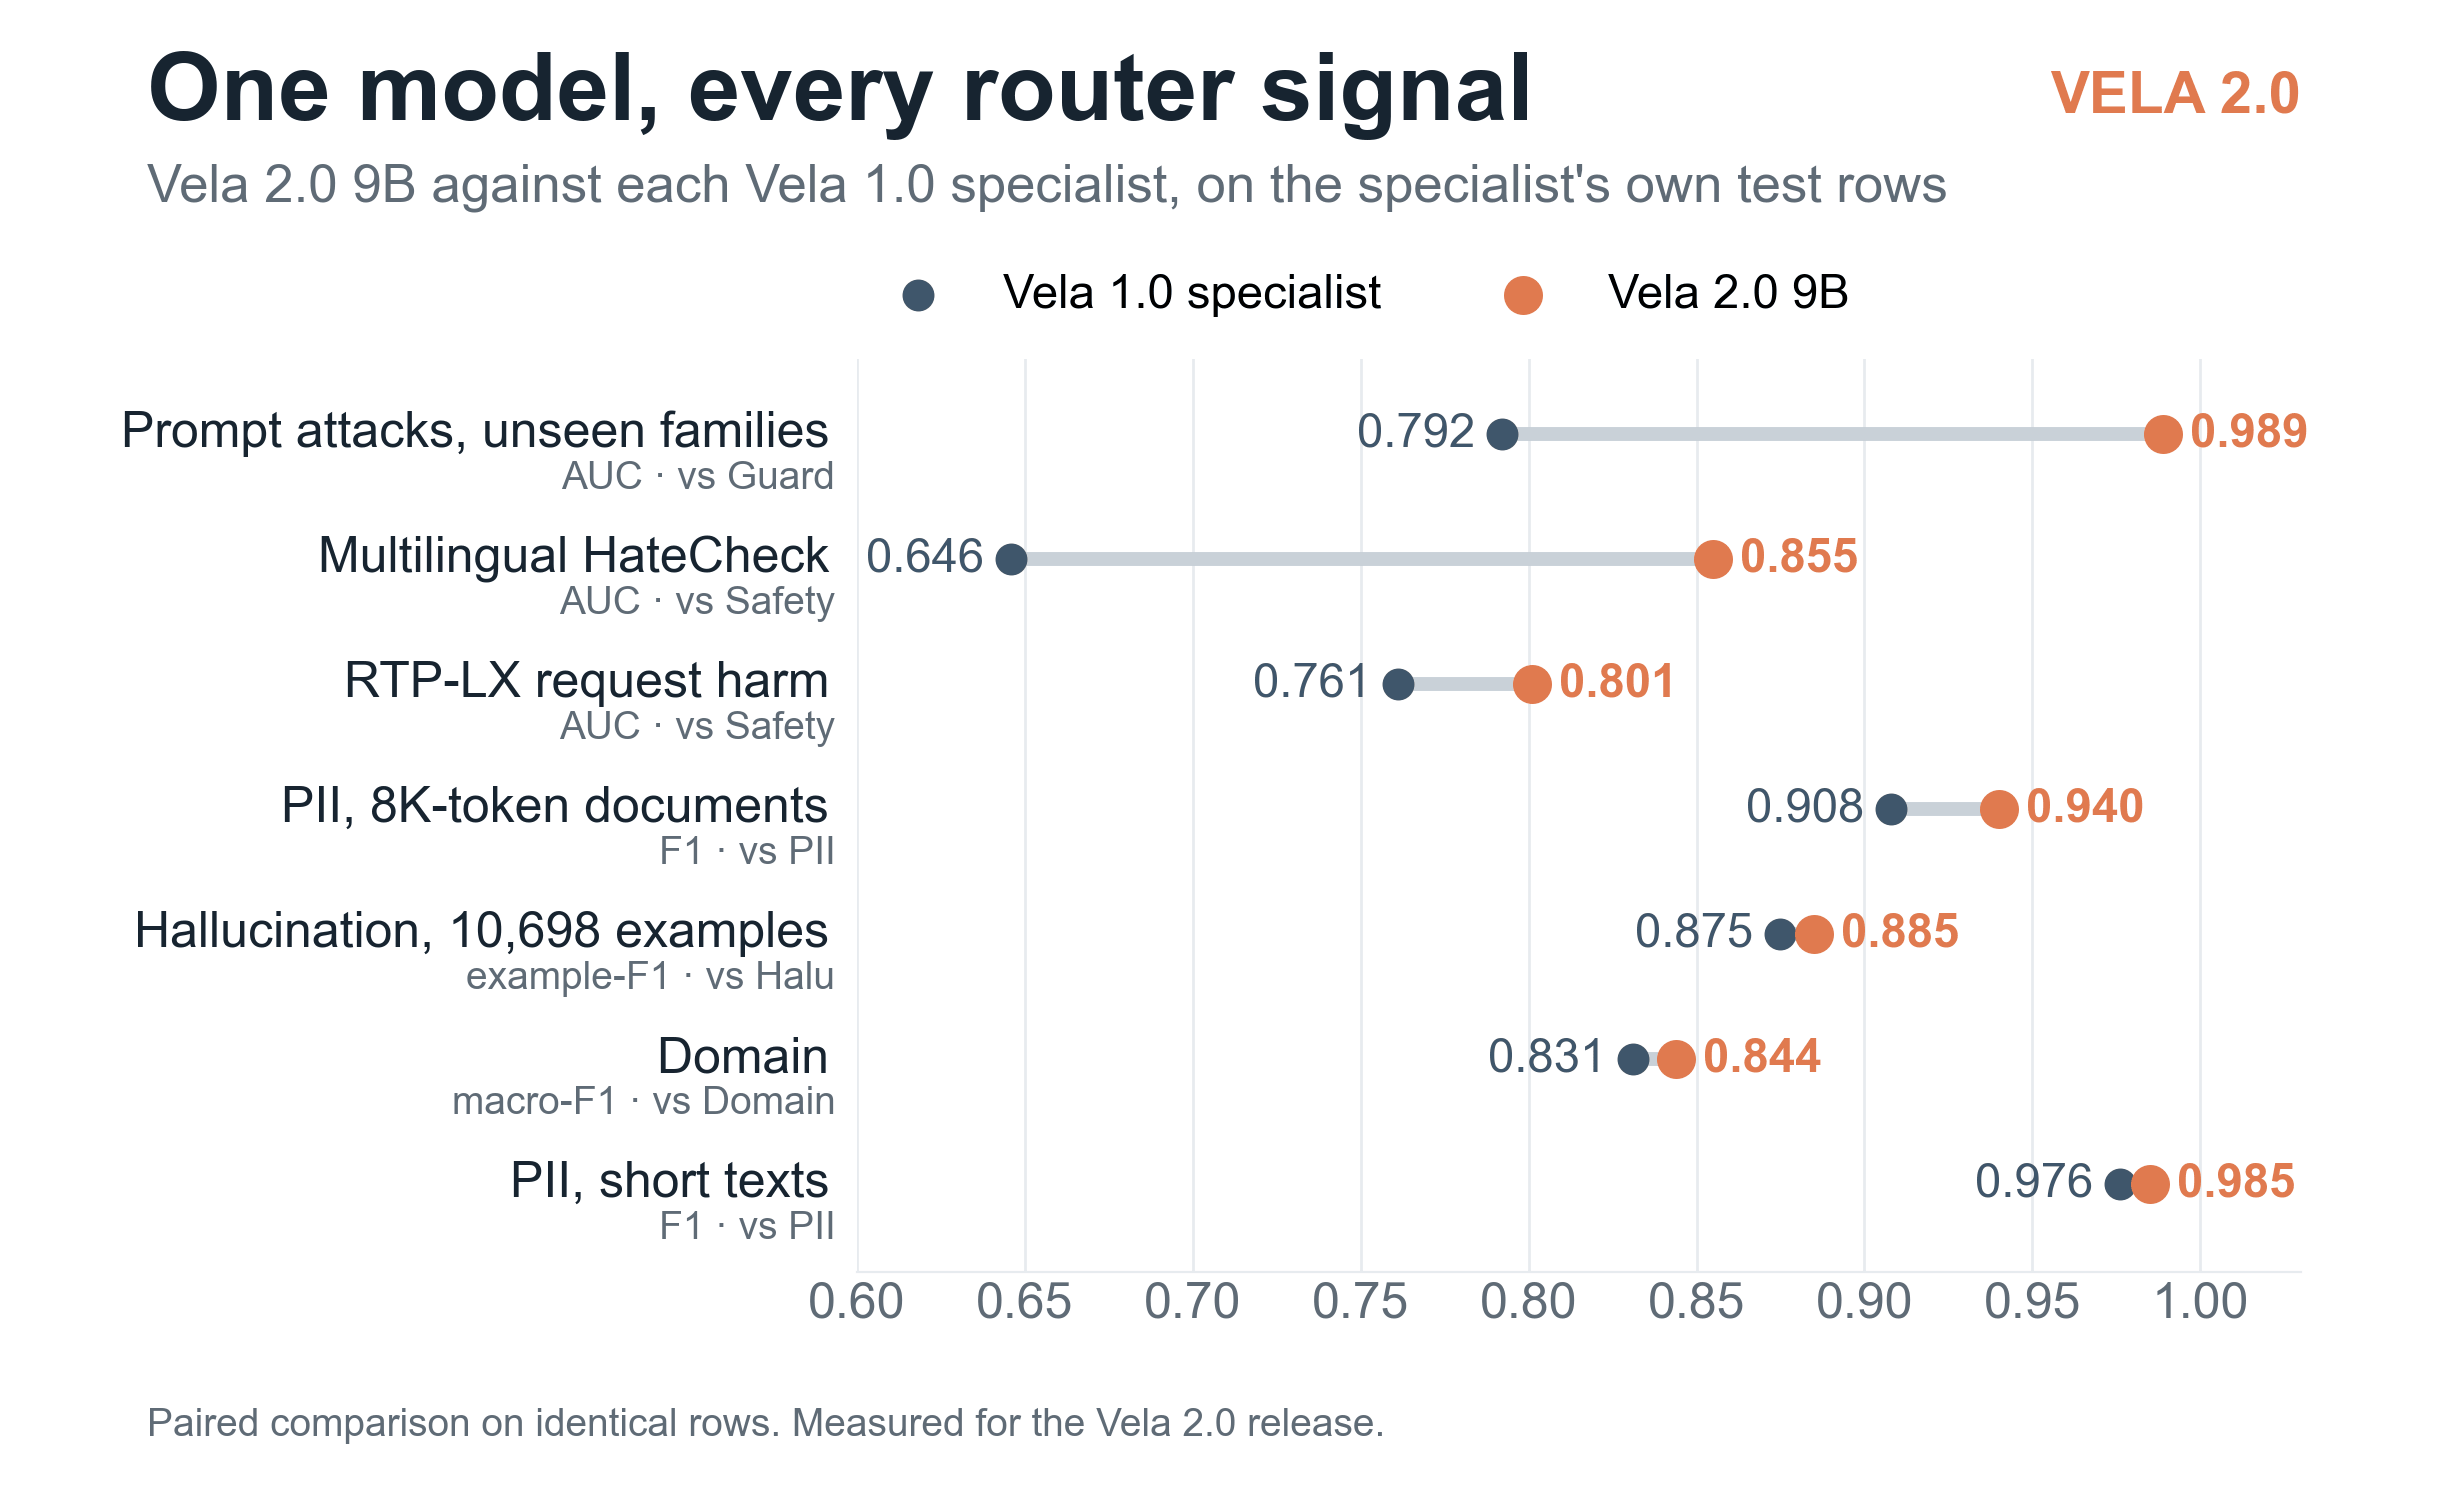
Router signals. One 9B model is ahead of or level with every Vela 1.0 specialist on the specialist's own test rows, and clearly ahead where specialists generalise worst: prompt attacks from unseen families (0.792 → 0.989 AUC, paired 95% CI +15.4 to +23.9 points) and multilingual hate speech (0.646 → 0.855). It also leads on RTP-LX request harm (0.761 → 0.801), PII in 8K-token documents (0.908 → 0.940 F1), hallucination spans (0.875 → 0.885 example-F1) and domain (0.831 → 0.844 macro-F1). The 0.3B encoder reaches 0.995 F1 on short-text PII, ahead of the Vela 1.0 PII model (0.976), and runs on CPU.
Safety across the family. Over 14 public safety and prompt-attack sets the four sizes reach a macro AUC of 0.871, 0.875, 0.921 and 0.921, against 0.704 for GLiNER2.5-Decide.
Hallucination. On the 2,700 RAGTruth test rows, the 9B reaches 0.774 example-F1, ahead of the LettuceDetect v2 encoder re-scored on the same rows (0.743, +3.1 points, paired 95% CI [+0.5, +5.4]), while answering every other routing question in the same call.
Open extraction. ACL-Verbatim asks for the exact sentences in a paper that support an answer, and it was held out of training. The broad head reaches 23.6 to 24.5 word-F1 at all three decoder sizes; no GLiNER-family model exceeds 7.0.
Cost. A full router request takes 0.09 s on an A40 for the 0.3B, 0.13 s for the 0.8B, 0.40–0.49 s for the 4B and 0.60–0.71 s for the 9B. That is one call for every signal, where Vela 1.0 needed one model per signal.
General decisions. On the Jev Decision Index 0.2.1 (38 benchmarks), the 9B reaches 41.09 against 46.23 for Lux-9B, keeping 89% of its base; the 4B keeps 74% and the 0.8B 79%. The harness reproduces the published Decision 2.0 scores within 0.1 points. On fast-decisions, the 9B scores 62.5 against 62.9 for GLiNER2.5-Decide, while also answering the router's safety and span questions.
Noul calibration. The Jev chart and table use noul_calibration=False. With it enabled, the model cards report 16.01 / 31.91 / 41.63 for 0.8B / 4B / 9B. This optional setting is separate from the router's trained safety thresholds.
Full numbers
Router signals against the Vela 1.0 specialists, on each specialist's own test rows. Differences are paired bootstraps over identical rows. PII uses the research scorer's per-length development thresholds, rather than the shipped runtime calibration.
| Task | Vela 1.0 | Vela 2.0 0.3B | Vela 2.0 9B | Δ 9B vs Vela 1.0 [95% CI] |
|---|---|---|---|---|
| Prompt attacks, unseen families (AUC) | 0.792 (Guard) | 0.882 | 0.989 | +19.8 [+15.4, +23.9] |
| Multilingual HateCheck (AUC) | 0.646 (Safety) | 0.662 | 0.855 | +20.9 [+20.3, +21.5] |
| RTP-LX request harm (AUC) | 0.761 (Safety) | 0.728 | 0.801 | +4.0 [+3.4, +4.5] |
| PII, short texts (F1) | 0.976 | 0.995 | 0.985 | +0.9 [+0.1, +1.9] |
| PII, 8K-token documents (F1) | 0.908 | 0.894 | 0.940 | +3.2 [−1.1, +7.0] |
| Hallucination, 10,698 examples (example-F1) | 0.875 | 0.848 | 0.885 | +1.0 [+0.4, +1.7] |
| Domain (macro-F1) | 0.831 | 0.825 | 0.844 | +1.3 [−0.3, +2.8] |
PII protocol. The 0.3B's 8K value above is 0.894 with the research scorer; its exported runtime gives 0.896 with the test-blind 0.001 threshold floor and 0.929 with the shipped floor selected after observing the test effect. For 9B, the table's short-text value is 0.985; shipped calibration gives 0.987. These protocols are documented in the model cards.
Open extraction with the broad head, every model scored by one harness. The harness reproduces the GLiFormer-base card on all seven NER sets and the GLiNER-large-v2.5 average within 0.2 points. Latency is the mean over 100 questions on one A40.
| Model | Zero-shot NER, 7 sets (F1) | ACL-Verbatim evidence (word-F1) | ms per question, 3K-token context |
|---|---|---|---|
| Vela 2.0 9B, broad head | 43.5 | 24.5 | 2,288 |
| Vela 2.0 4B, broad head | 40.7 | 24.4 | 1,499 |
| Vela 2.0 0.8B, broad head | 28.9 | 23.6 | 477 |
| GLiFormer-large | 63.6 | 7.0 | 930 |
| GLiNER-large-v2.5 | 61.3 | 4.6 | 496 |
| GLiNER2.5-Decide | 51.5 | 2.3 | 415 |
| GLiNER2.5-small | 42.5 | 4.6 | 197 |
General decisions on the Jev Decision Index 0.2.1 (38 benchmarks), with noul_calibration=False.
| Size | Decision 2.0 base | Vela 2.0 | Kept |
|---|---|---|---|
| 0.8B | 20.14 (Eos-0.8B) | 16.01 | 79% |
| 4B | 42.55 (Nox-4B) | 31.63 | 74% |
| 9B | 46.23 (Lux-9B) | 41.09 | 89% |
Four sizes, one interface
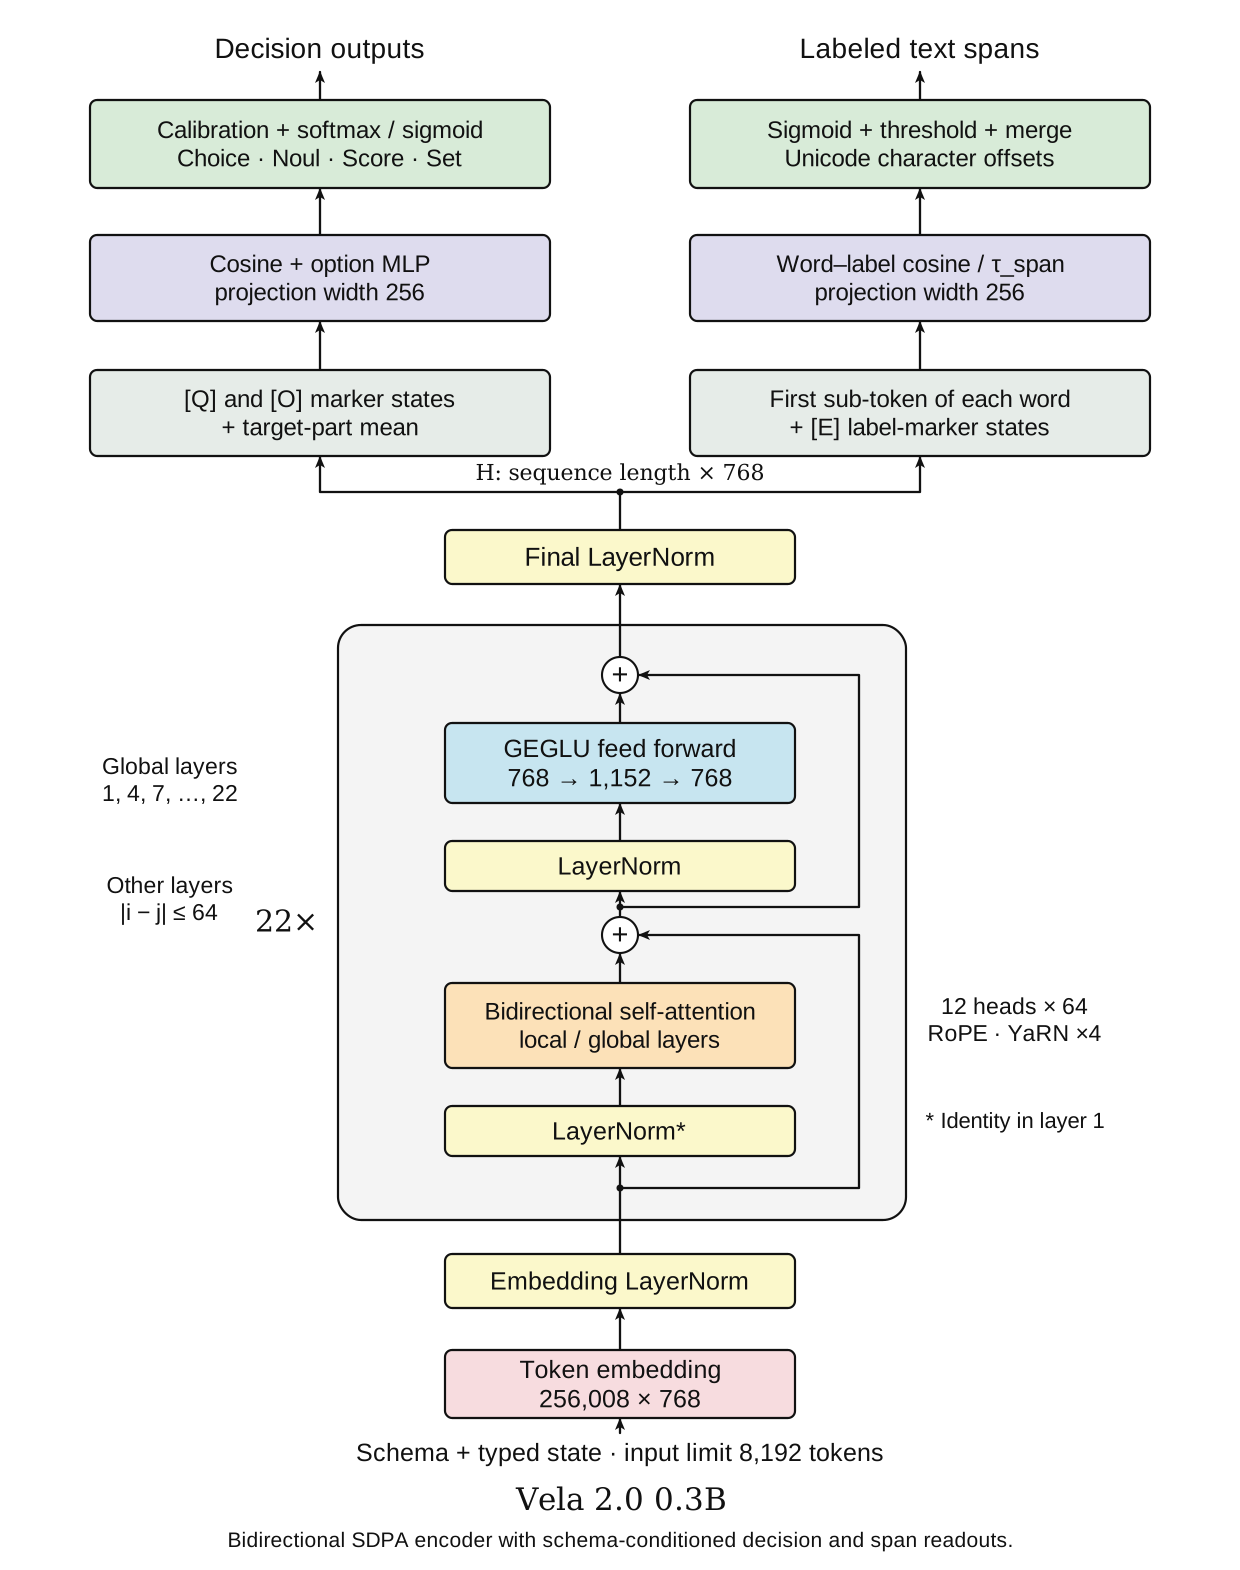
The four checkpoints share the question format, with independently trained backbones and readout weights. The 0.3B supports CPU and ONNX deployment; the hybrid models add the broad span head through the same interface.
Backbone and readout operators
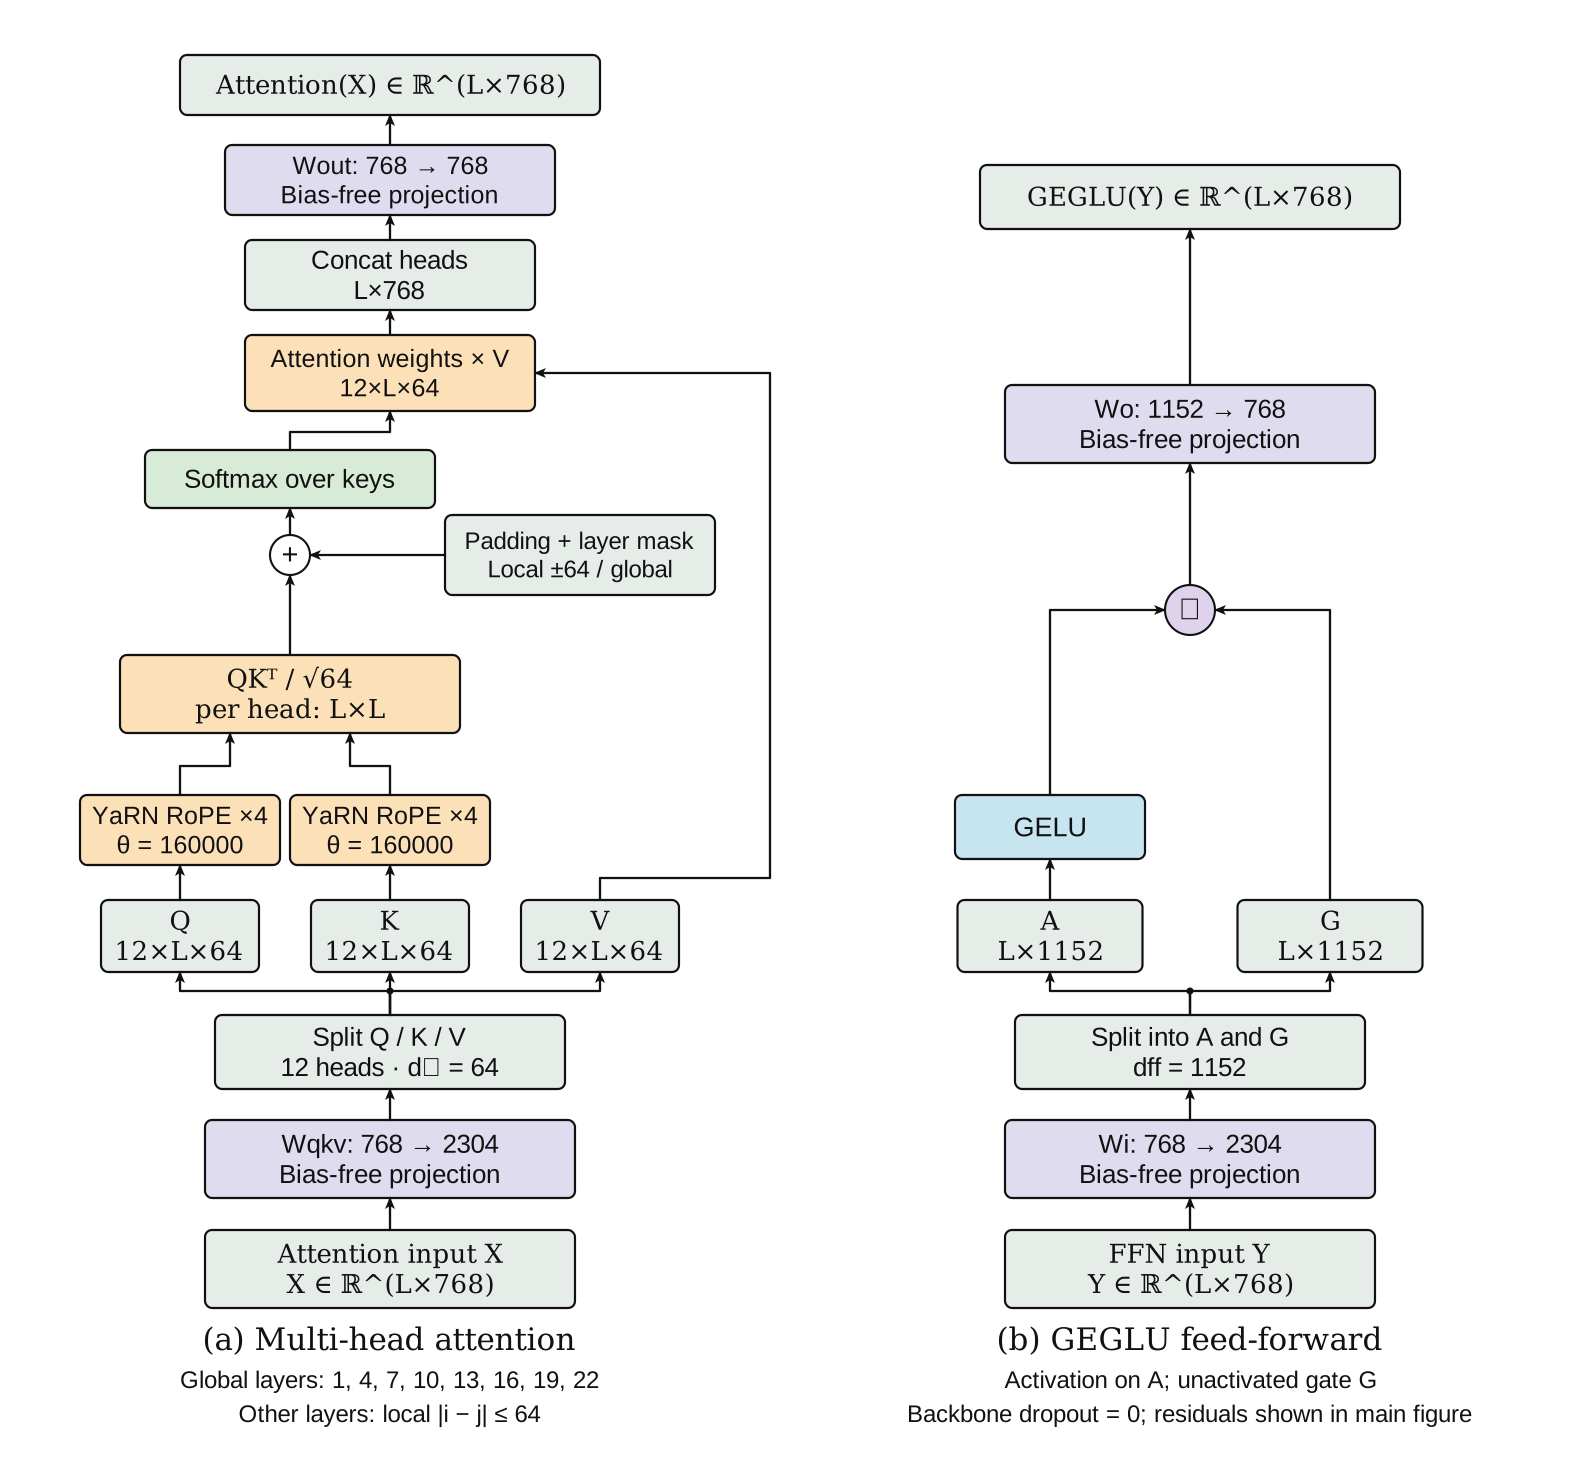
The backbone diagrams expand the attention, recurrence, gating and feed-forward operators behind the four model views.
The readout differs between the encoder and the decoders even though the client interface stays the same.
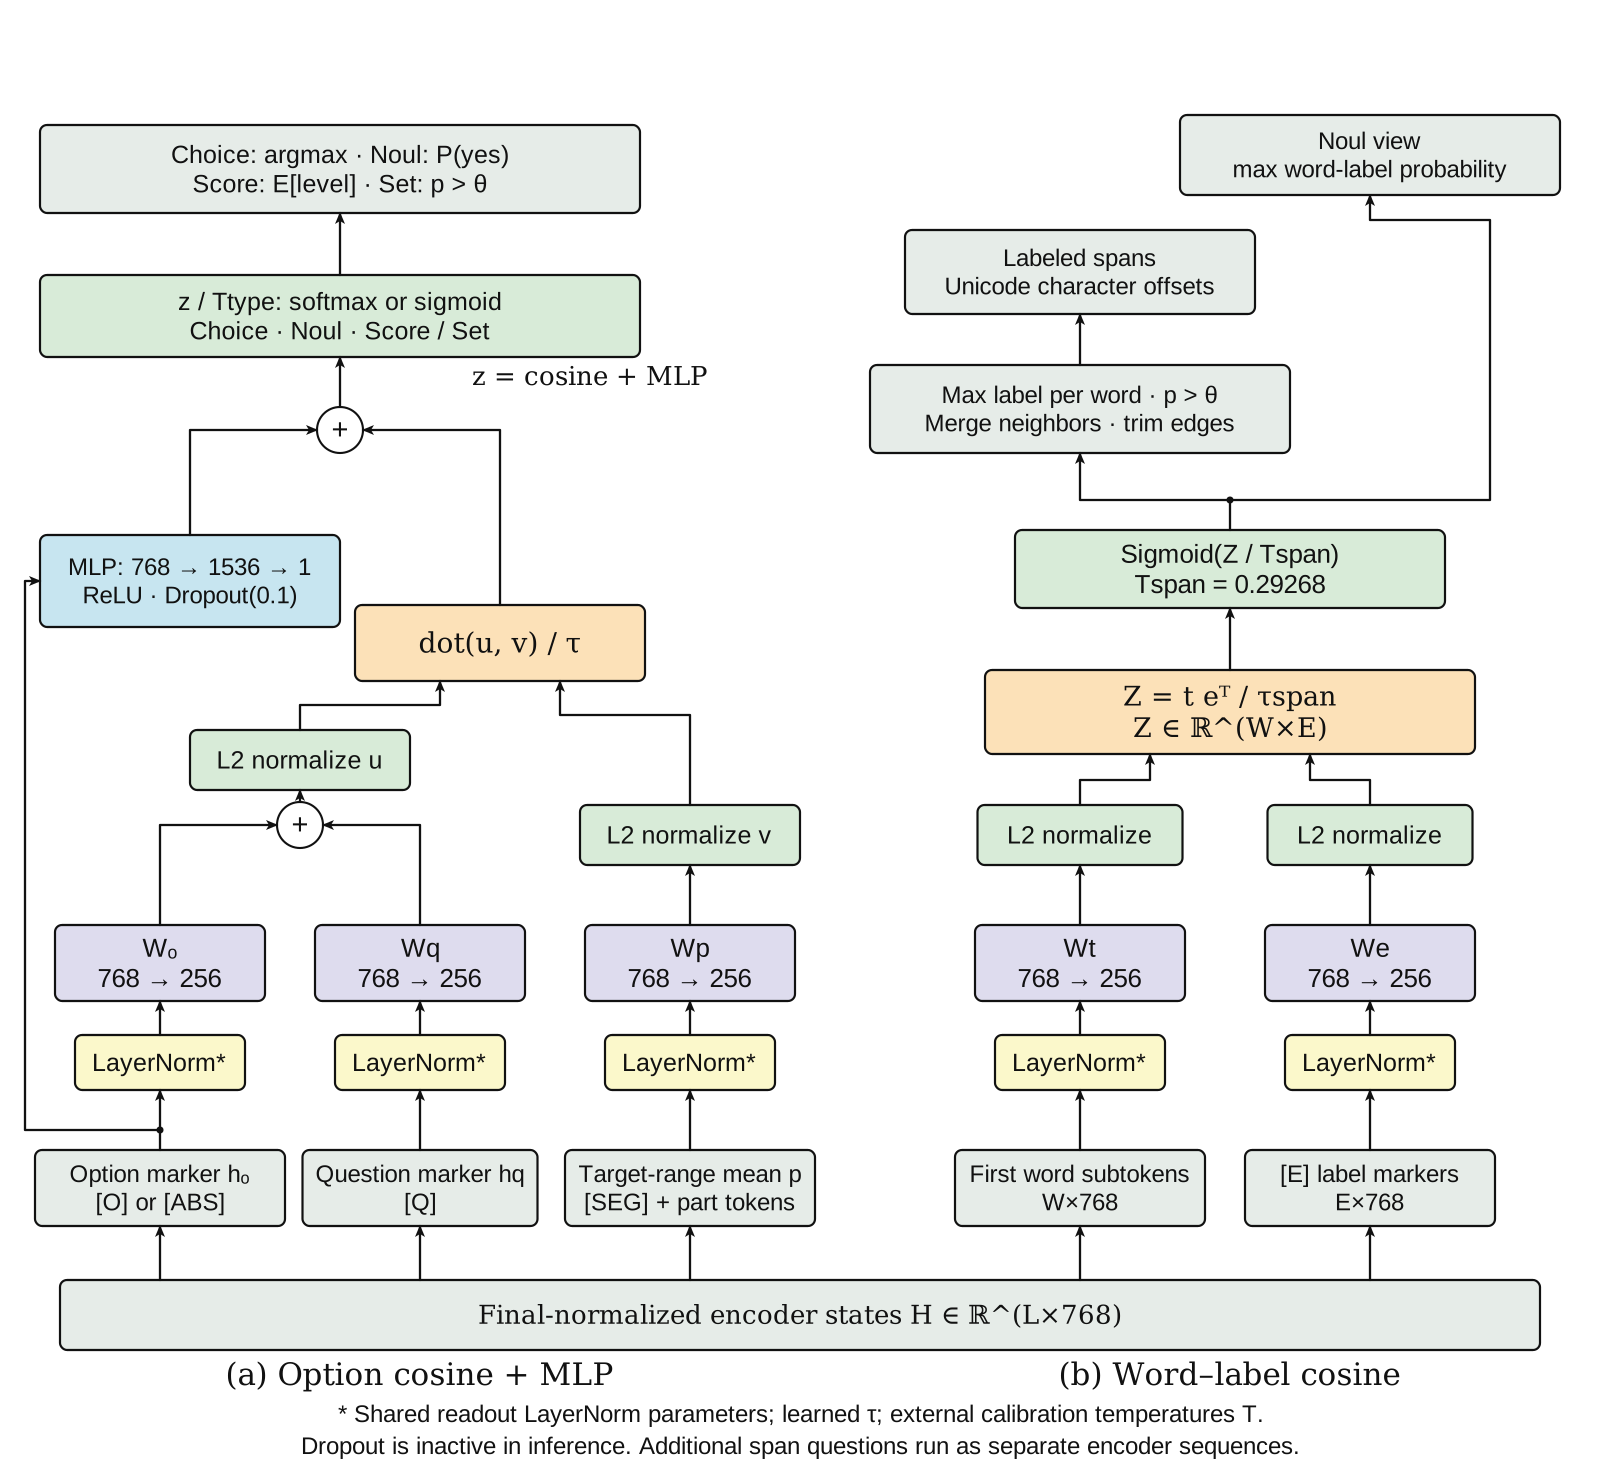
The diagrams trace the public system_one() path at fixed model revisions. Source notes and editable SVG generators accompany the figures.
Training
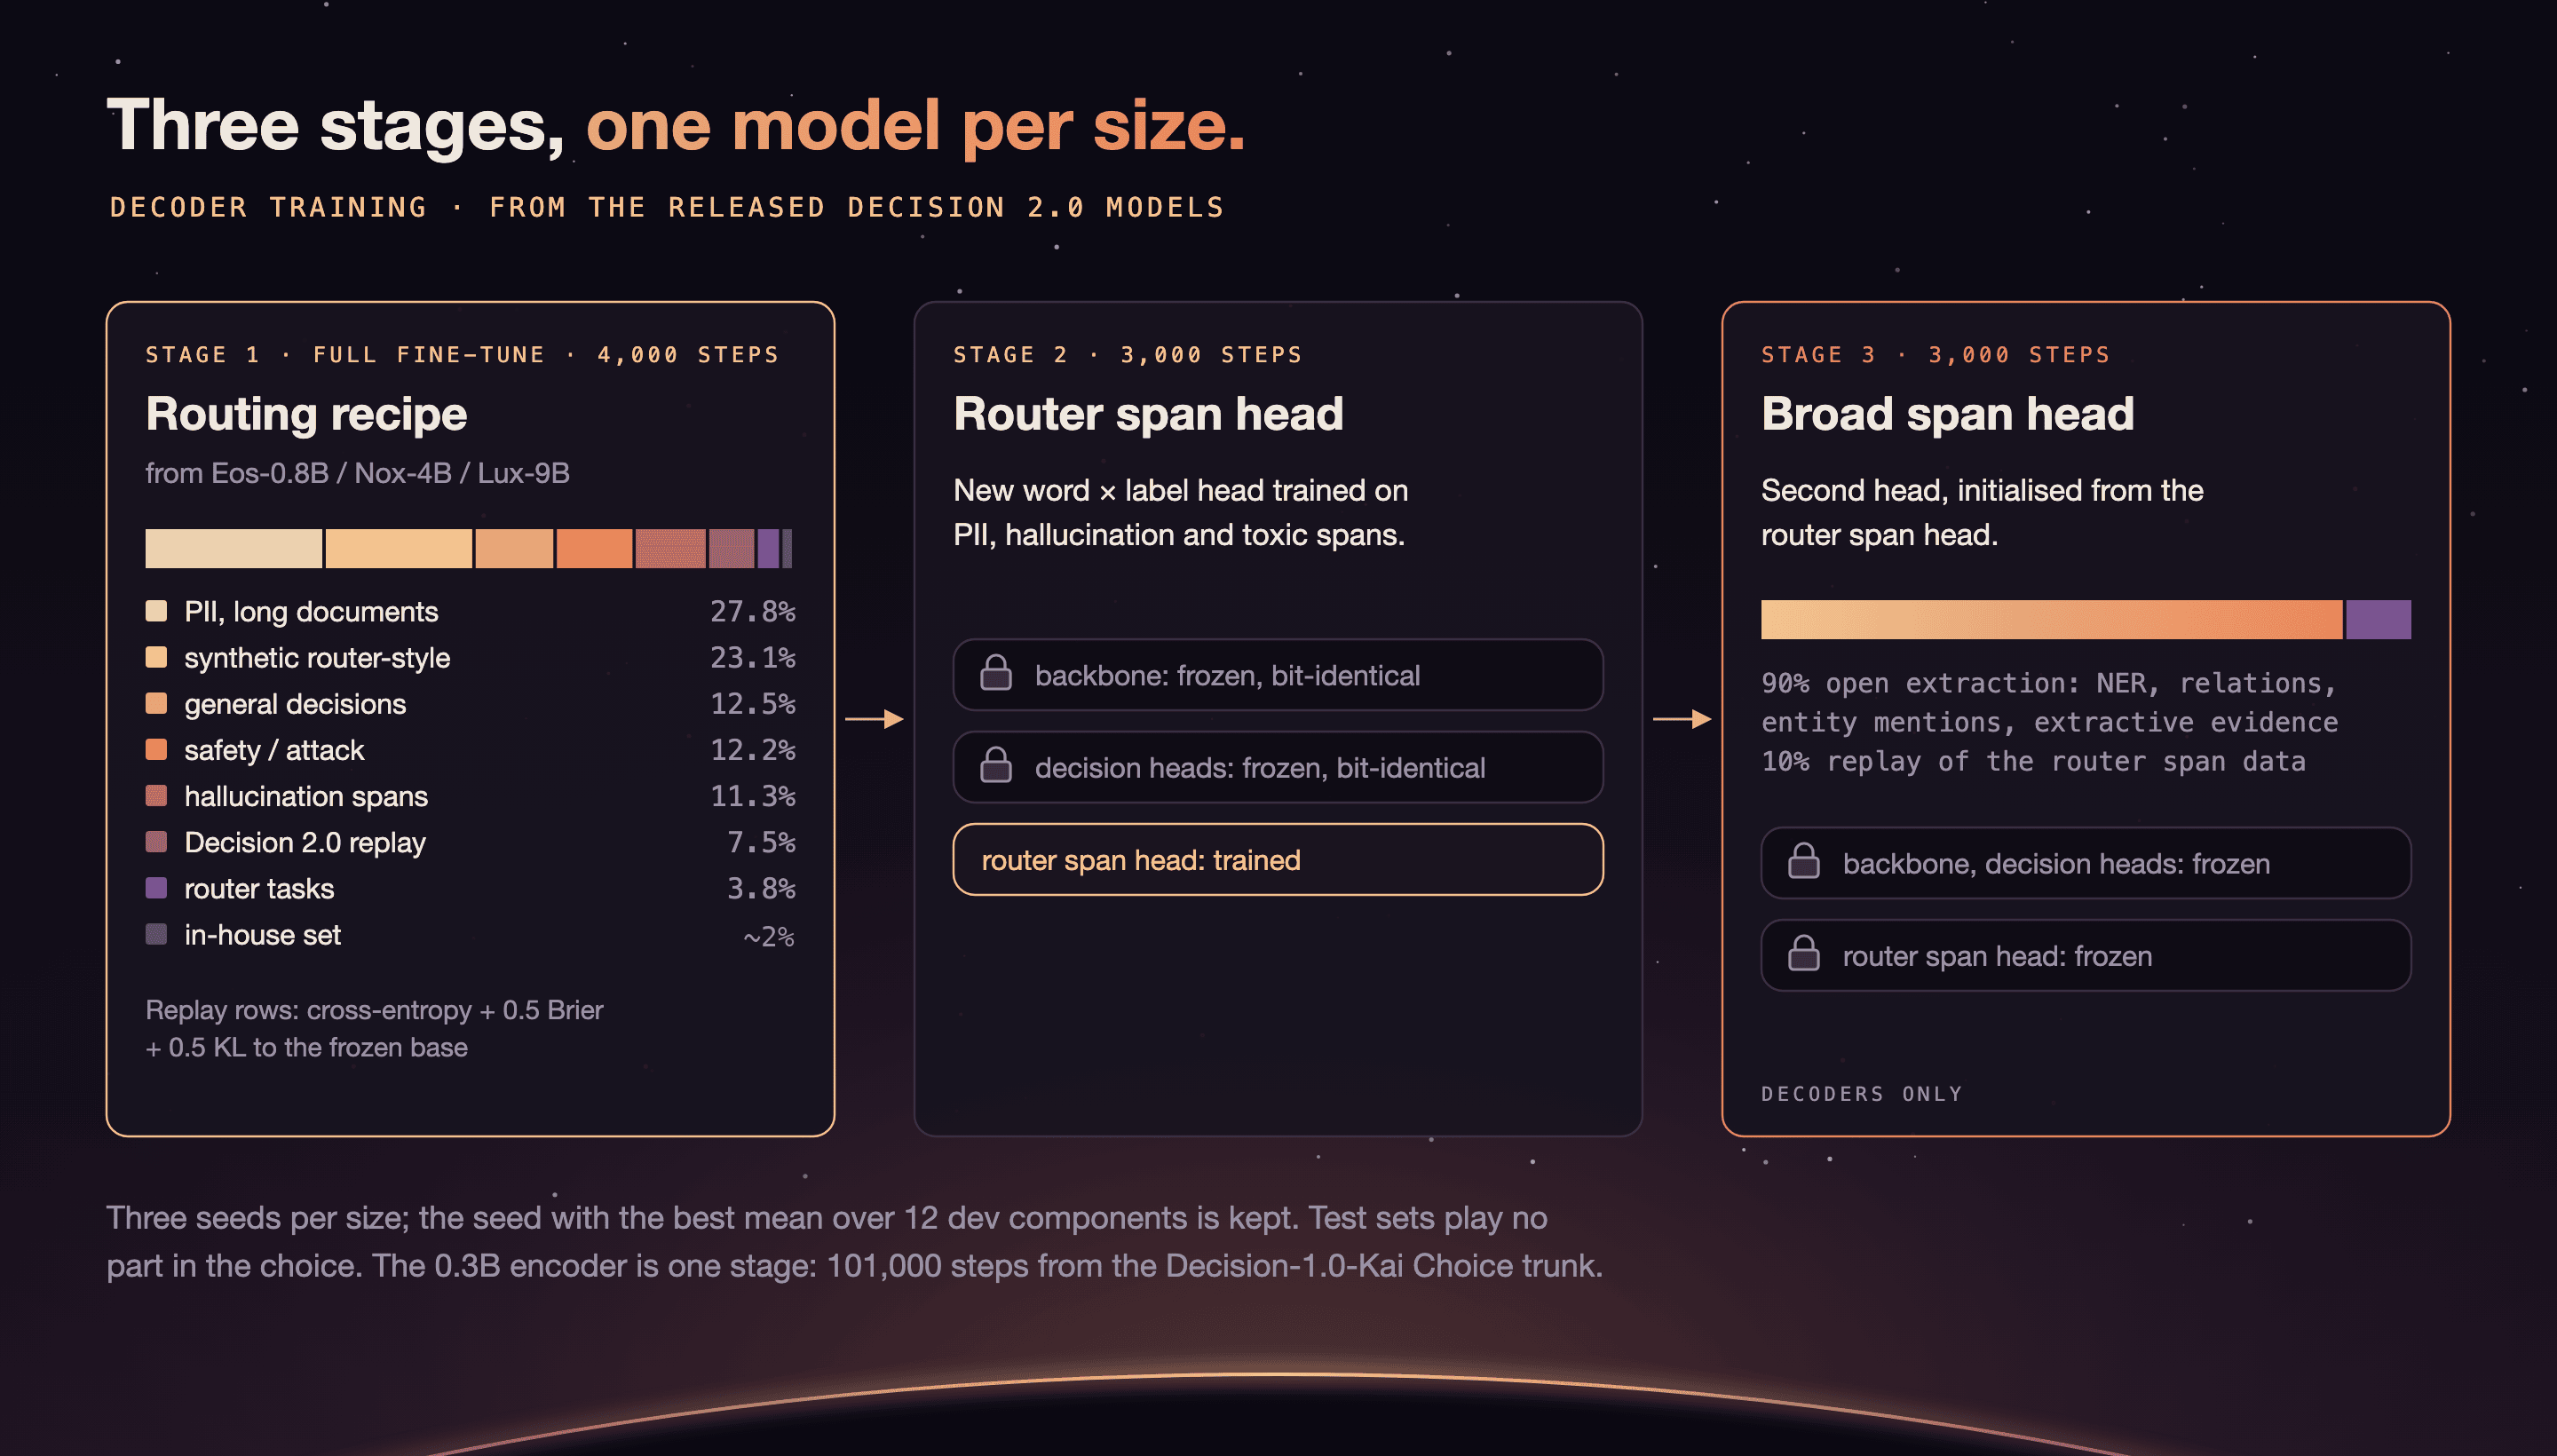
The decoders train in three stages from the released Decision 2.0 models. Each later stage freezes everything trained before it.
All four sizes use shared signal families and schema resampling. Sources become parts, typed questions and answers; options are anonymised, dropped and paraphrased so the model learns to read labels.
The hybrid models train in three stages:
- Routing recipe. Fine-tune the whole Decision 2.0 base for 4,000 steps, with a KL term on replayed base-model rows to retain general decisions.
- Router spans. Train the router span head on the frozen backbone.
- Open extraction. Train the broad head with everything else frozen: 90% named entities, relations, entity mentions and extractive evidence; 10% router span replay. Evidence sources include the training splits of SQuAD 2.0, HotpotQA and Natural Questions.
The 0.3B encoder trains in one stage of 101,000 steps from Kai's Choice trunk, about 6.9 hours on one AMD MI325X.
Stage-1 data mix
| Data | Sources | Share of steps |
|---|---|---|
| Long-document PII, 17 types | generated, train-only pool of 10,457 documents | 27.8% |
| Synthetic router-style decisions | 304,593 rows, 63,043 labels, 21 languages, generated with Qwen3-30B-A3B-Instruct-2507 | 23.1% |
| General decisions | SNLI, BoolQ, ARC, MASSIVE, TyDi QA and other Decision 1.0 source families, in our own wording | 12.5% |
| Safety and prompt attacks | AEGIS 2.0, PolyGuardMix, Nemotron-Safety-Guard v3, LLMail-Inject, Salad-Data | 12.2% |
| Hallucination spans | LettuceDetect prose and code data, including the RAGTruth train split | 11.3% |
| Decision 2.0 replay | Decision 2.0 training rows, with a KL term to the frozen base | 7.5% |
| Router tasks | Global-MMLU, Aya, DiffusionDB, WildFeedback, router PII recipe, Presidio replay | 3.8% |
| Small in-house set | ~2% |
A synthetic row is kept only when a blind re-label agrees with it (71% do). Training rows are deduplicated against every evaluation set. Each size was trained with three seeds, with checkpoint selection on development rows. The 0.3B final release selection also considered test results, as noted with the evaluation protocol above.
Try it
With the same dependencies installed, use a hybrid model on GPU to combine request routing, PII and unsupported-claim spans:
from transformers import AutoModel

m = AutoModel.from_pretrained("vllm-sr/Vela-2.0-9B", trust_remote_code=True).to("cuda")
PII_LABELS = m.vela2_engine.cal["pii_schema"]["labels"]   # the 17 trained PII types

result = m.system_one(
    state={"request": "Hi, I'm Tom Baker (tom.baker@example.com). What is the maximum daily dose of paracetamol for an adult?",
           "source": "For adults, the maximum dose of paracetamol is 4 grams in 24 hours, taken as 500 mg to 1 g every 4 to 6 hours.",
           "answer": "Adults can take up to 6 grams of paracetamol in 24 hours, in doses of 500 mg to 1 g every 4 to 6 hours."},
    questions={
        "pii": {"type": "span", "instructions": "Which spans are personal information?",
                "criteria": PII_LABELS, "over": "request"},
        "halu": {"type": "span", "instructions": "Which spans of the answer are not supported by the context?",
                 "criteria": {"unsupported": "a claim not supported by the context"}},
        "domain": {"type": "choice", "instructions": "Which subject area is this request about?", "over": "request",
                   "criteria": {"health": "medicine, clinical practice, nutrition, ageing or sexual health",
                                "math": "arithmetic, algebra, geometry, statistics or other mathematics",
                                "other": "a subject that fits none of the listed areas"}}})
Two span questions and a Choice, one call. The decoder evaluates the two span questions in separate rendered sequences. The recorded output (trimmed):
{
  "answers": {
    "pii": {"type": "noul", "noul": 1.0},
    "halu": {"type": "noul", "noul": 0.996},
    "domain": {"type": "choice", "choice": "health", "confidence": 0.977}
  },
  "spans": {
    "pii": [{"label": "PERSON", "start": 8, "end": 17, "text": "Tom Baker", "probability": 0.999},
            {"label": "EMAIL_ADDRESS", "start": 19, "end": 40, "text": "tom.baker@example.com", "probability": 1.0}],
    "halu": [{"label": "unsupported", "start": 22, "end": 29, "text": "6 grams", "probability": 0.982}]
  },
  "span_heads": {"pii": "router", "halu": "router"}
}
Any other label set goes to the broad head. Asking "Which spans of the context answer the request?" over a product description returns March 2024 (0.997) and 499 euros (0.865) for "When did the X200 go on sale, and at what price?". A set question returns every label above its threshold, for example both billing and shipping for "My card was charged twice and the parcel never arrived."
Each model also ships vela2_serve.py, a small FastAPI server for the same request on POST /v1/systemone:
pip install fastapi uvicorn
python vela2_serve.py --model . --device cuda --port 8001
Towards open foundation routing models
Vela 2.0 brings routing decisions and span answers into one model family. The next step is native signal-backend integration in vLLM Semantic Router, replacing per-signal classifiers with one Vela 2.0 request.
- Models: Vela 2.0 collection (0.3B, 0.8B, 4B, 9B)
- Decision 2.0 bases: Eos-0.8B, Nox-4B, Lux-9B
- Paper: Vela 2.0: Towards Open Foundation Routing Models, forthcoming
License. Weights, code and documentation are Apache-2.0. The 0.3B tokenizer carries the Gemma Terms of Use; training data retain their source licenses, including CC-BY-SA share-alike terms. Each model card links its notices and license scope.
We thank the Decision 2.0 team for releasing the base models openly; the label resampling follows GLiNER2's recipe.